Task · Environment · Agents

From Prescribed to Emergent: Representing and Exploiting Structure in LLM Agents Collaboration

A structural representation that makes emergent LLM-agent collaboration explicit - tasks, environment, and agents on one record - without prescribing agent reasoning, behavior, or communication order. Infuse turns that record into a better collaboration policy.

1Carnegie Mellon University·2George Washington University·3Zoom·4University of Arizona
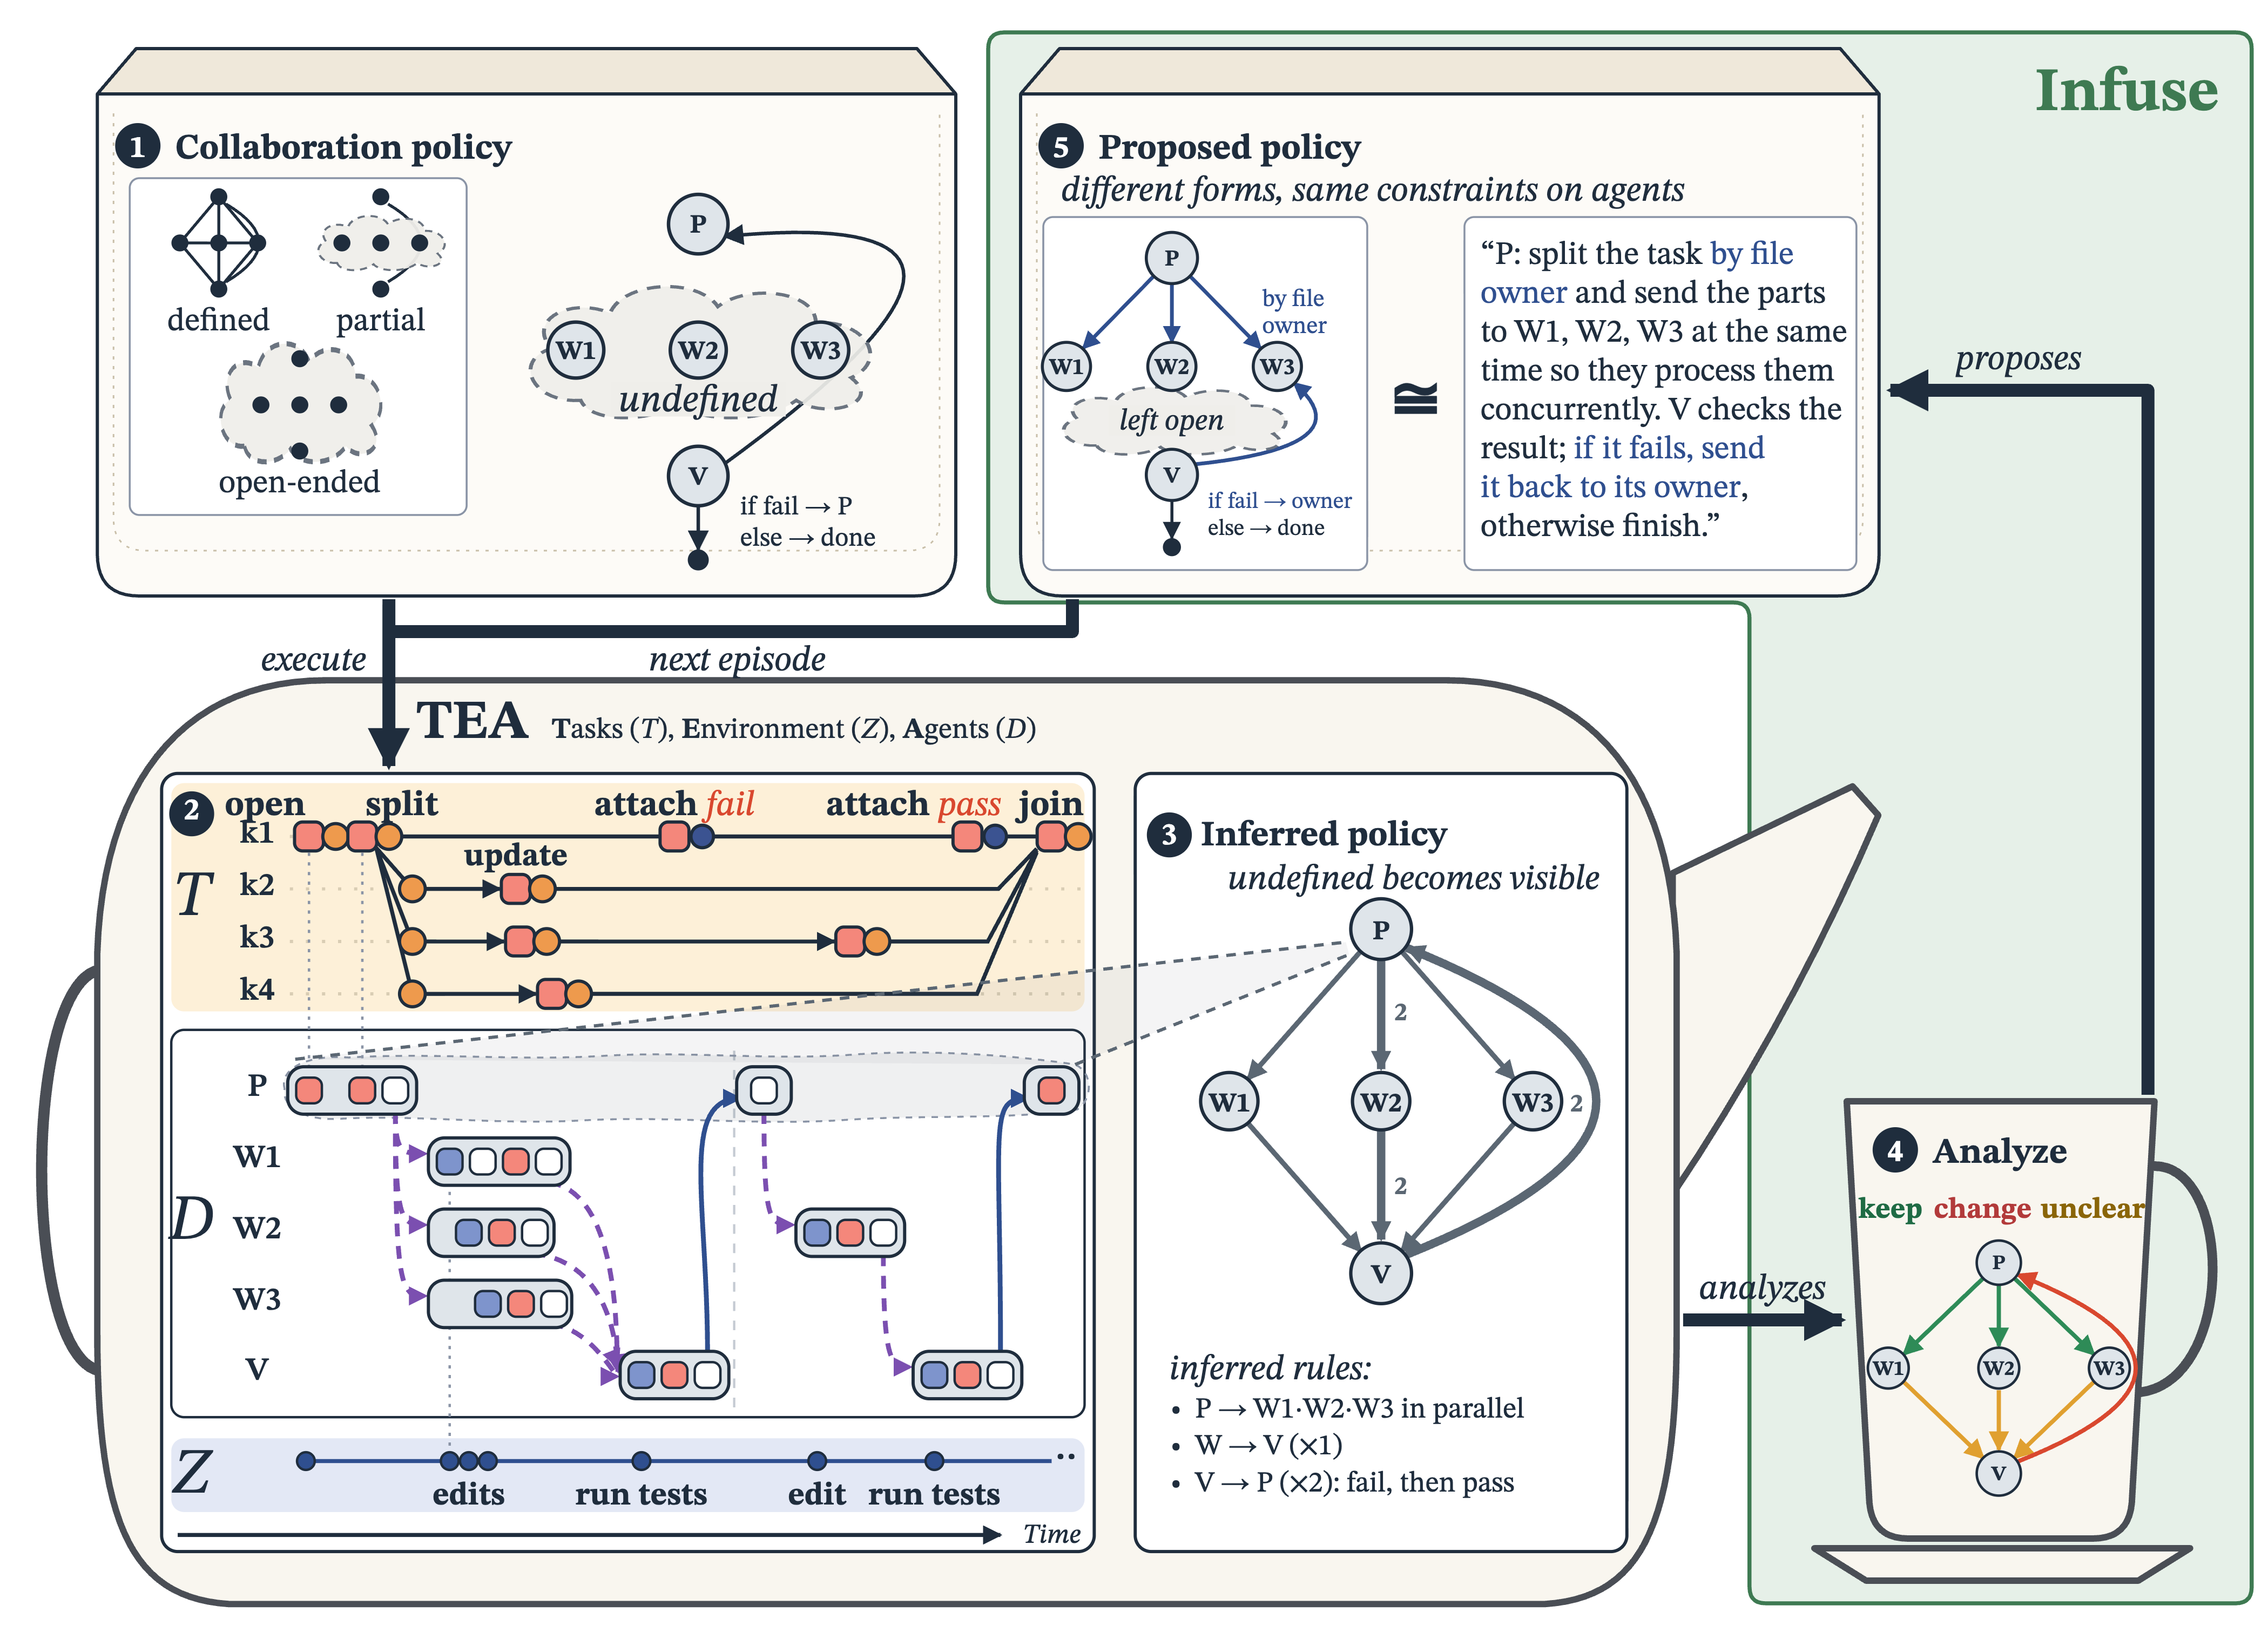
Roll out → unroll. Live execution rolls the scroll out, writing the collaboration onto three lanes: tasks (T), agent activations and messages (D), and the environment (Z). As the scroll closes, each agent's activations merge into a node and messages are tallied into weighted edges - the recovered topology and rules. Infuse then unrolls the record to reflect: it queries the record to see why each part of the recovered policy helped or hurt, keeps, revises, or leaves each part open, and pours out an updated policy Γ′ for the next episode.

Collaboration Structure Emerges During Execution

A collaboration policy - an executable graph, or code and instructions - rarely controls everything. Agents deviate from workflows, orchestrators decompose work on the fly, and in open-ended settings agents organize collaboration themselves. Flexibility helps performance, but the structure that emerges is hard to track, and therefore hard to improve.

TEA and Infuse overview: a collaboration policy is executed, TEA records task evolution, environment outcomes, and agent interactions, a policy is inferred from the record, analyzed, and an updated policy is proposed for the next episode
TEA and Infuse. (1) A collaboration policy Γ may fully, partially, or minimally specify coordination. (2) TEA combines views of Task evolution, Environmental outcomes, and Agent interactions; solid edges are prescribed by the policy, dashed edges emerge from agents. (3) Aggregation and trace analysis recover and discover the topology and candidate execution rules. (4) Infuse queries these records to assess coordination against task progress and environmental outcomes, and (5) proposes an updated policy Γ′ to execute.
1

TEA represent · recover/discover

TEA couples an Agent Interaction Graph (asynchronous activations and events) to a Task Activity Graph (immutable task versions and the actions that create them) and the shared environment, attributing task changes to activations and evidence to exact versions. Merging activations into nodes and counting messages per edge recovers the topology; activation timing and message paths expose the execution rules, including the ones the policy never specified.

2

Infuse analyze · improve

Infuse queries the record to check the recovered policy against task progress and environmental outcomes: which parts helped, which hurt, and which never showed an effect. Each part is kept, revised, or left open, and the result is an updated policy Γ′ for the next episode. Starting from an empty policy, one Infuse update improves task performance in both benchmarks, code refactoring and Silo-Bench. A separate agent writes Γ′ as lessons for the team and for each agent.

Task-Environment-Agents

DT = (D, T, Z, Φ, U)    interaction graph · task graph · environment · evidence attachments · tool space

Task Activity Graph TAG (T)

Task versions and the actions that create them. A version carries a persistent identity, a goal and evaluation rule, and a state. Versions are immutable, so branching and merging work keeps its full history.

Agent Interaction Graph AIG (D)

Events and activations. An activation is one reasoning cycle of an agent: its interval, received events, and ordered tool calls with results. Events carry any payload and can wake other agents.

Shared Environment Env (Z)

The world agents observe and change. Environment calls return fresh events into the AIG, so task declarations and evidence stay tied to externally verifiable effects.

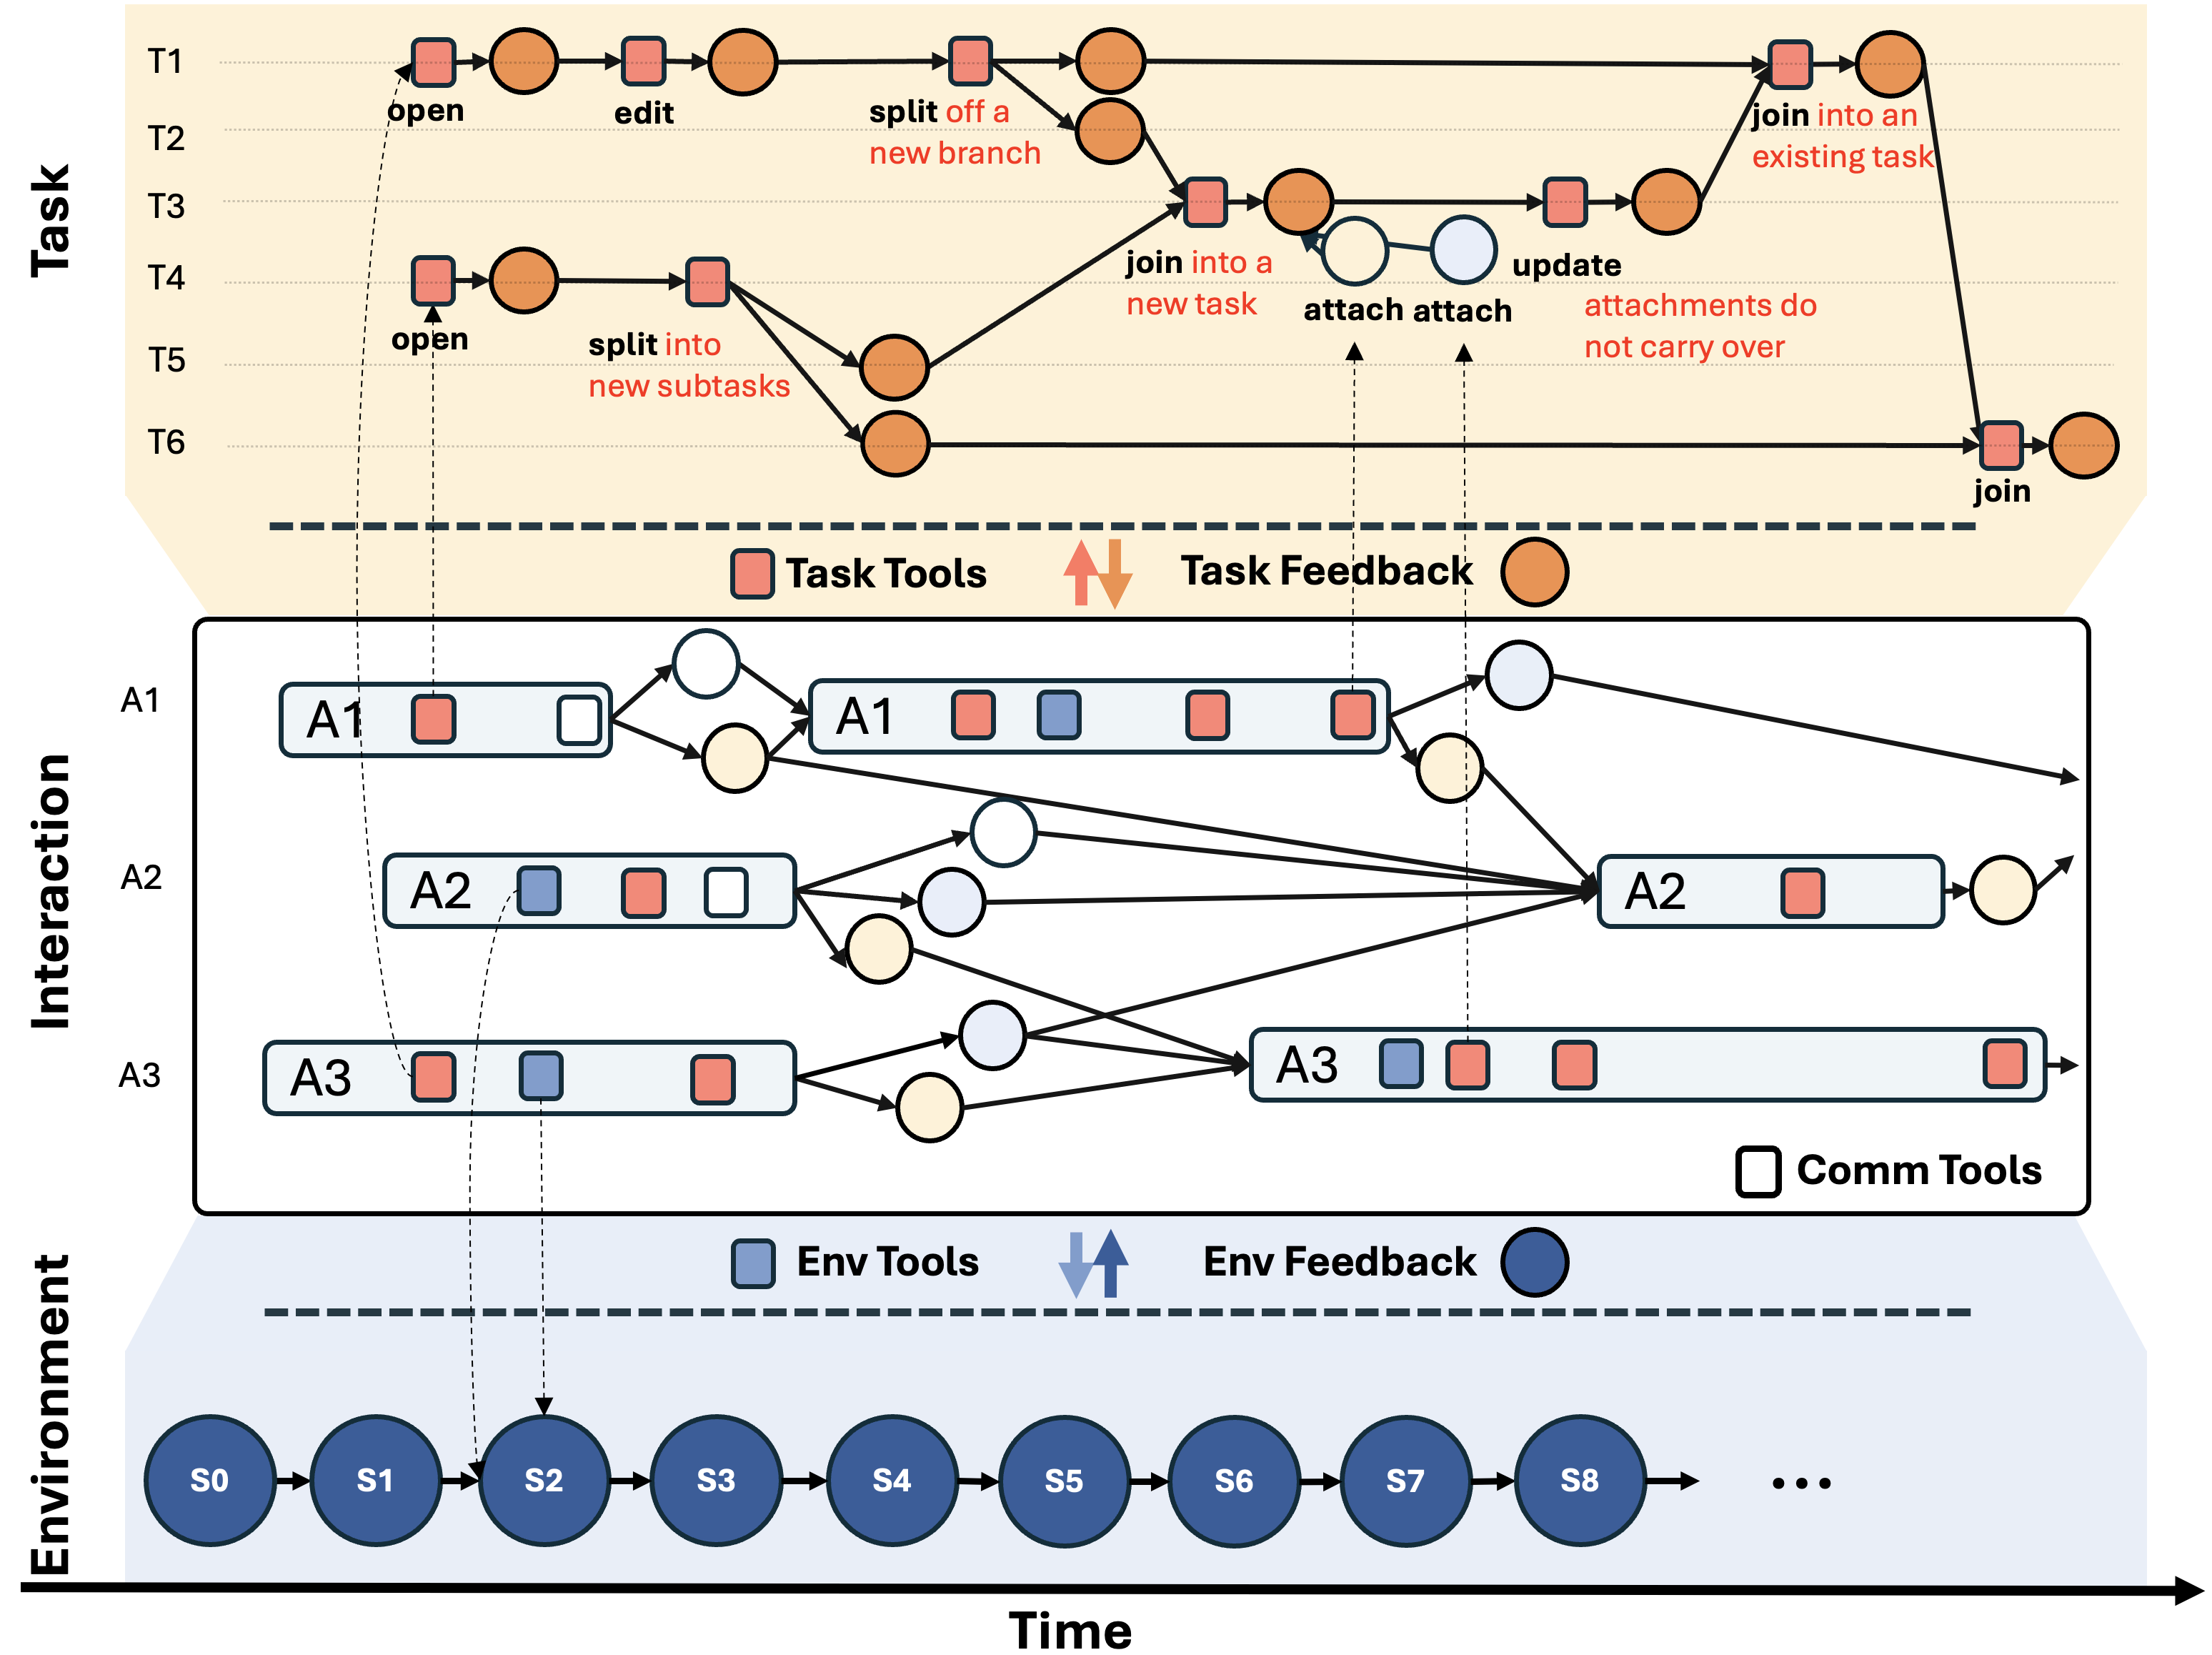
The three layers of TEA: task rows with versions and actions on top, agent activations exchanging events in the middle, and environment state transitions at the bottom, aligned over time
The three layers, aligned over time. Task rows hold versions (orange circles) and actions (squares). Wide rectangles are activations, inner squares are tool calls, circles are events. The environment row records state transitions. Every tool call is recorded in its issuing activation; task and environment calls additionally update the task graph and the environment, tying the layers together.

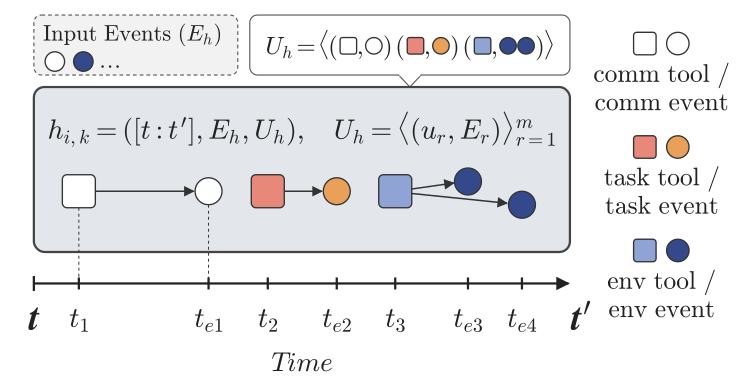
AIG one activation

One AIG activation: input events, a time interval, and an ordered sequence of tool calls each paired with returned events
One activation. Agent i's k-th activation hi,k = ([t:t′], Eh, Uh) records its input events, its duration, and the ordered tool calls ur, each paired with the events Er it returned.

TAG six task tools

OPEN(δ, σ)∅ → q

Create a fresh task identity with an initial version.

EDITδ(q, δ′)q → q′

Revise the goal or evaluation rule while preserving the reported state.

UPDATEσ(q, σ′)q → q′

Change the reported state while preserving the task specification.

SPLIT(q, {(kj, δj, σj)})q → {q1, …, qm}

Decompose one version into versions with distinct task identities.

JOIN({qj}, k′, δ′, σ′){q1, …, qm} → q′

Integrate versions from distinct identities into a single successor version.

CLOSE(k)propagate closure

Closure propagates backward through recorded ancestry; a split's parent closes only when all of its children are closed.

Coupled transitions

Besides task and environment tools, TEA provides sendh(e, J), which delivers an event to agents J (a new message or a forwarded event), and attachh(φ), which attaches evidence φ = (h, x, q) to an exact task version. Evidence stays with that version and does not carry over to later revisions. For a task version q, the attached evidence, its providers, and its content together provide signals of task progress; interpretations from different agents may agree, partially agree, or disagree, and different interpreters may weight sources differently.

Tool callAIGTAGEnv.Evidence
task tool u ∈ UTD′T′ZΦ
environment tool u ∈ UZD′TZ′Φ
attachh(φ)D′TZΦ′
sendh(e, J)D′TZΦ

TEA transitions: highlighted cells are updated by the call.

Recovering and Discovering the Collaboration Policy

A collaboration policy is an interaction topology plus coordination rules. Given a TEA record, aggregate the activations in a window by agent: agents become nodes, and message counts become edge weights. Activation timing and message paths then reveal execution order, parallel overlap, repetition, conditional routing, and joins.

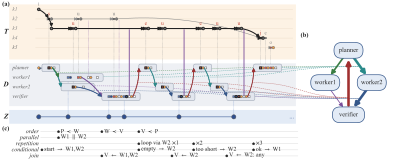
A TEA trace generated by a hidden collaboration policy, the interaction graph recovered from it, and the execution rules inferred as the record grows
Recovering a hidden policy. (a) Task evolution (T), agent activity (D), and environment transitions (Z) recorded under a hidden collaboration policy. (b) The interaction graph recovered by aggregating activations by agent, with edges weighted by interaction frequency. (c) Execution rules inferred as the record grows (P: planner; W: workers; V: verifier). Asking "who worked on task k2, and why?" traces back to the planner splitting k1, messaging both workers, and worker1 acting in the environment first.

Topology recovery. Take the activations that start and finish within a window [t, t′] and merge them by agent. The result is a weighted graph G[t,t′] = (V, E, w) whose edges connect agents that exchanged messages, weighted by message counts. The full topology is recovered once the records cover every edge the policy can create.

Execution rules. Consecutive activations whose starts fall within τ of each other and whose intervals overlap are grouped. For completed activations with start sh and finish fh: h ≺ h′ iff fh ≤ sh′ (execution order), and h ∥τ h′ iff |sh − sh′| ≤ τ (overlap). Along activation paths these give sequential, parallel, repeated, conditional, and join rules, including ones the policy never specified; a worked example is in the paper.
Infuse: From the Record to a Better Policy

TEA is also the interface through which agents communicate, transform tasks, and act in the environment. Infuse takes the trace of an episode - starting from an empty policy - and proposes the next one.

1

Execute and record

DT ← fexecute(V, Γ)

The team V attempts the task under policy Γ, and TEA records the collaboration as it unfolds.

2

Recover / discover

Γ̂ ← frecover(DT)

Aggregate activations by agent to recover the observed topology and infer candidate execution rules.

3

Analyze and propose

Γ′ ← fanalyze(Γ, Γ̂, DT)

Query the record to compare the recovered policy with the trace, assess coordination against task progress and environmental outcomes, and decide what to keep, add, revise, or leave open.

In the paper's implementation, a separate gpt-6-sol agent consolidates this guidance into global lessons for the team and private lessons for individual agents, forming Γ′. Infuse itself is agnostic to how Γ′ is produced.

Agents run on TEA asynchronously. In each activation an agent acts on its environment view, its task-graph view, received messages, and private memory, and every tool call is recorded. An agent ends its own activation after a round of reasoning, can sleep and reactivate after a delay, and is activated by an incoming message; a sender can also interrupt an active recipient, ending its activation and starting a new one with the message.

Results

Two domains, five gpt-5.6-terra agents with no predefined roles: code refactoring (modularize a redundant codebase; LoC reduction while passing fixed tests, six repositories, 100-step budget) and Silo-Bench (30 distributed reasoning tasks where every agent must answer a query that needs the whole team's information). A separate gpt-6-sol agent derives the Infuse guidance.

Representation experiments

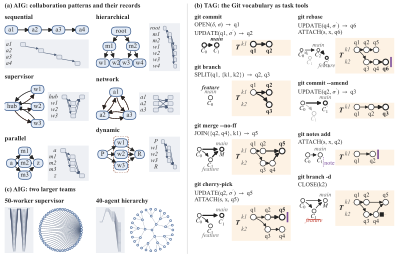
Six collaboration patterns with their AIG traces, Git operations expressed as TAG task tools, and AIG records of a 50-worker supervisor and a 40-agent hierarchy
Interactions and task history. (a) Interaction graphs and AIG traces for six LangGraph collaboration patterns. (b) TAG is a general-purpose task representation: individual or composed task actions express Git's collaborative coding semantics - commits, branches, merges, rebases, reverts, amends, notes, and branch deletion. (c) AIG represents teams of any size, illustrated by a 50-worker supervisor and a 40-agent hierarchy.

Does the shared task graph help?

Access to TAG and to direct communication is ablated in four conditions.

Code (shop)Silo-Bench
SettingPass ↑Rall ↑Rpass ↑Success ↑S ↑P ↑
TAG + comm4/546.943.00.770.810.85
TAG only3/535.335.20.770.810.83
Comm only3/520.219.50.600.730.78
Neither4/521.320.80.030.150.20

Code refactoring on shop: five runs per condition; Pass counts runs passing all tests; Rall and Rpass are mean LoC reductions (%) over all and passing runs. Silo-Bench: 30 tasks; S is the fraction of exactly correct answers, P the partial-credit score. Best values in bold.

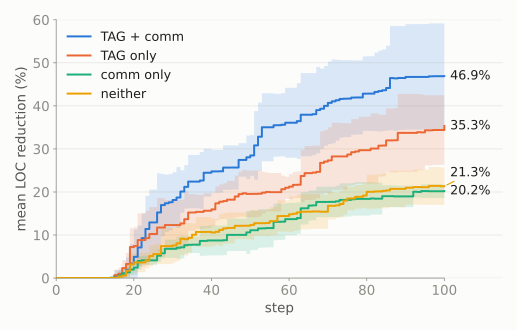
Mean LoC reduction over agent steps on the shop repository for the four ablation conditions, with standard-deviation shading
LoC reduction over agent steps on shop: mean of five runs per condition, shading ±1 SD. The gap between the TAG conditions and the others widens during execution.

TEA's shared task graph outperforms direct communication alone on both benchmarks, while combining the two yields the strongest overall results.

Does Infuse improve the policy?

TEA with and without one Infuse update, five runs per repository and condition.

0.63 → 0.70
Average pass rate across the six refactoring repositories.
25.5 → 30.4%
Repository-average LoC reduction among passing runs; it rises in all six repositories.
0.77 → 0.83
Silo-Bench success with TAG + comm.
0.81 → 0.86
Silo-Bench exact correctness S with TAG + comm.

Infuse enables TEA to refine its collaboration policy from experience and improve overall task performance.

Read more: full Infuse tables, communication patterns under ablation, and five rounds of Infuse

Code refactoring before (TEA) and after one Infuse update (Inf.)

EasyMediumHardAverage
Codebaseshopplanledgerfreightstaypayroll
TEAInf.TEAInf.TEAInf.TEAInf.TEAInf.TEAInf.TEAInf.
Pass rate ↑ 0.800.80 0.800.80 0.600.80 0.600.80 0.400.60 0.600.40 0.630.70
LoC reduction (%) ↑ 43.0±10.256.6±8.9 28.3±5.931.6±3.7 22.1±3.425.1±1.7 20.6±4.022.1±3.5 20.2±2.624.8±4.4 18.8±2.522.2±9.0 25.5±9.230.4±13.3

Average is the unweighted repository mean; ± denotes sample SD across passing runs, or across repositories for Average. Better paired values in bold; ties unbolded. Pass rates rise on ledger, freight, and stay, remain unchanged on shop and plan, and only fall on payroll.

Silo-Bench before (TEA) and after one Infuse update (Inf.), 30 tasks

TAG + commTAG onlyComm onlyNeither
TEAInf.TEAInf.TEAInf.TEAInf.
Success ↑0.770.830.770.730.600.670.030.17
S ↑0.810.860.810.750.730.790.150.19
P ↑0.850.880.830.780.780.820.200.24

Bold marks the best value in each row. Infuse raises success in three of four settings; TAG-only success slightly falls from 0.77 to 0.73.

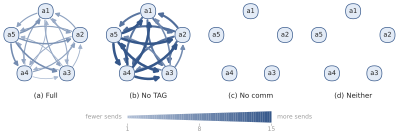
Interaction graphs of the five agents summed over five seeds for the full, no-TAG, no-communication, and neither conditions; the last two are empty
Who sent to whom under ablation, summed over five seeds per setting on one scale. Removing TAG raises traffic rather than lowering it: 244 events over 20 edges without TAG against 94 over 20 with it. Panels (c) and (d) are empty by construction - with send removed, there is no edge to draw.
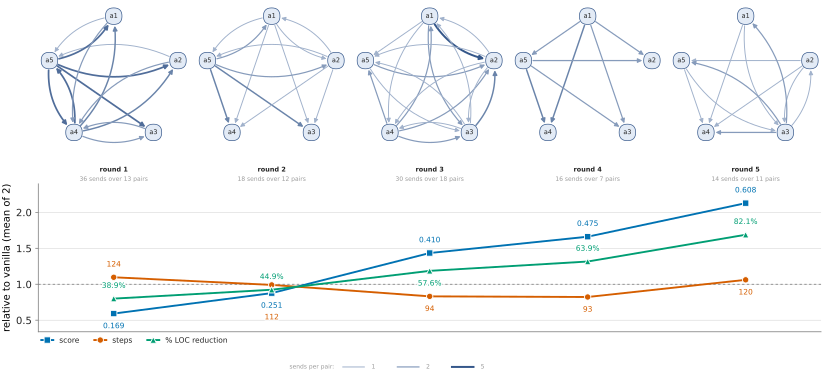
Five rounds of Infuse updates: the team's interaction graph in each round and score, steps, and LoC reduction relative to the vanilla setting
Iterating Infuse over five rounds. Top: the team's interaction graph in each round as it inherits the previous round's lessons. Bottom: score, steps, and LoC reduction relative to the vanilla setting.

Back to top